Vector databases explained for product owners
Vector databases explained for product owners
By Marco Lopes · Published March 9, 2023 · AI & Machine Learning
Vector databases are appearing in more conversations about AI products. They promise better search, more relevant recommendations, and a way to connect language models with business information. For product owners, however, the useful question is not whether the technology is interesting. It is whether it solves a problem worth funding.
At Kordspace, we work as a remote collaborative studio across software, AI, Web3, hardware, and design. We approach vector databases as one component in a product system, not as a product strategy by themselves.
In this guide, we explain what they do, where they fit, and how we would evaluate them before committing to a production architecture.
What is a vector database?
A vector database stores and searches vectors: ordered lists of numbers that represent information. In AI applications, those numbers commonly come from an embedding model, which converts text, images, or other inputs into numerical representations.
The important idea is proximity. An effective embedding model places related items near one another in its numerical space. A search system can then find nearby items rather than relying entirely on matching words.
Imagine a support article titled “Recover access to an account.” A customer searches for “I forgot my login details.” A keyword system might struggle if the wording does not overlap. An embedding-based system can potentially connect the two because their meanings are related.
A vector database does not understand a business in the human sense. It provides efficient similarity search over representations produced elsewhere. The quality of those representations matters as much as the database itself.
How is this different from a normal database?
Traditional databases are excellent at precise questions: which orders belong to an account, which invoices remain unpaid, or which products cost less than a specified amount.
Vector search answers a different question: which stored items are most similar to this input?
Rather than checking equality, it compares vectors using a measure such as cosine similarity, dot product, or distance. The appropriate measure depends on the embedding model and how its outputs are prepared.
At larger scales, systems often use approximate nearest-neighbor indexes. These trade some retrieval accuracy for lower latency and lower computational cost. The closest result is not always guaranteed to be returned.
We generally keep transactional data in its existing database and introduce vector search alongside it. Similarity search should not replace reliable accounting, inventory, or permissions logic.
What does the search pipeline look like?
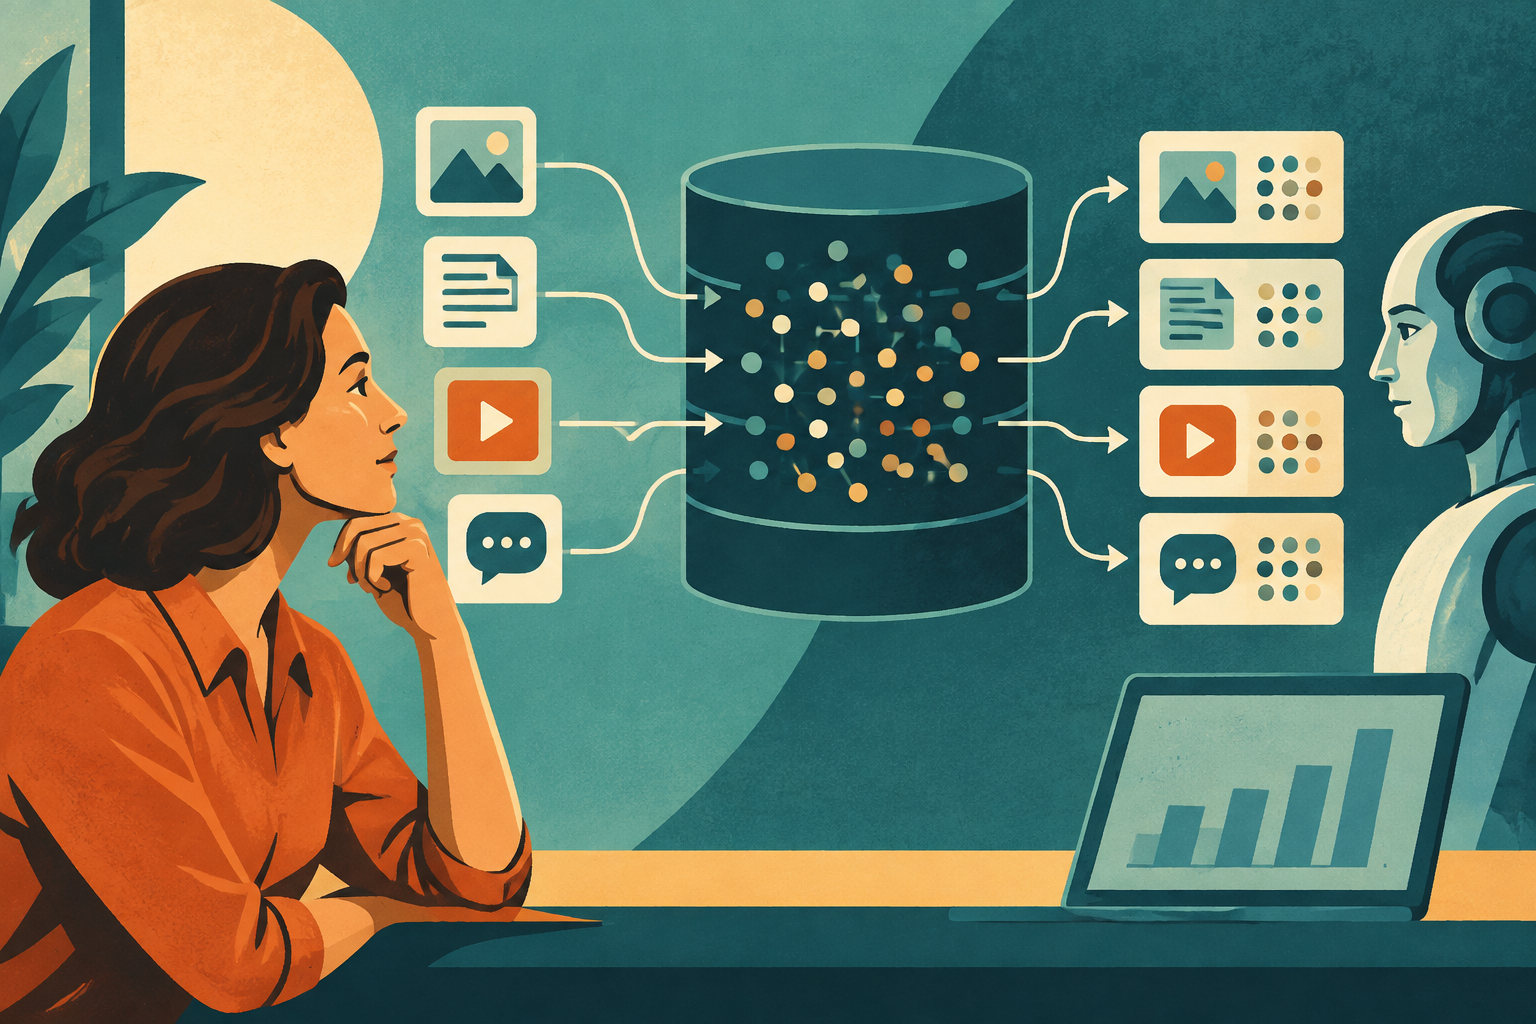
The complete workflow is easier to understand than the terminology suggests:
- Collect content. We gather approved documents, product descriptions, images, or other source material.
- Prepare it. We clean the data and, for long documents, divide it into useful passages.
- Generate embeddings. An embedding model converts each item or passage into a vector.
- Store searchable records. We associate vectors with identifiers and metadata, such as source, language, owner, and update time.
- Process a query. We embed the search input using a compatible model and retrieve nearby vectors.
- Apply product logic. We enforce access rules, optionally rerank candidates, and present the underlying content.
The database is therefore only one part of the feature. Ingestion, content quality, permissions, and interface design determine whether the experience is useful.
Which product problems are good candidates?
We look for situations where users express intent differently from the language stored in a system.
Knowledge search is a strong candidate. Teams might need to find a policy, troubleshooting guide, or engineering note without remembering its exact title.
Product discovery can benefit when shoppers describe an intended use instead of selecting a precise category. Similarity can help identify candidates, while structured filters enforce price, availability, or compatibility.
Recommendations can use embeddings to find related content or products, especially when descriptions provide useful signals. Similarity alone, however, is not a complete recommendation strategy: popularity, diversity, and user preferences may still matter.
Related-item discovery can help group similar support tickets or identify potentially duplicate documents. We would treat the results as suggestions until their reliability is established.
The common thread is fuzzy relevance, not exact truth.
When should we avoid vector search?
Not every search problem needs embeddings. If users primarily search by order number, product code, email address, or an exact legal phrase, conventional indexes may be more appropriate.
A small, well-organized dataset may also work perfectly well with basic full-text search and good filters. Adding an embedding service and a vector index introduces operational work that must earn its place.
We are particularly cautious when similarity is mistaken for a decision rule. Two components can have similar descriptions while having incompatible electrical specifications. Two policies can sound alike while applying to different jurisdictions.
For many products, a hybrid approach is more sensible: keyword search handles exact language, vector search handles semantic relationships, and structured rules enforce hard constraints. We still need to test how those results are combined.
How does this connect to language models?
A vector database can help a language-model application retrieve relevant information before generating an answer. This pattern is commonly called retrieval-augmented generation, or RAG.
For example, we can retrieve passages from an approved knowledge base and include them in the model's prompt. The model then has relevant source material available when composing its response.
This does not train the model on those documents, and it does not guarantee a correct answer. Retrieval can select the wrong passages. The model can misinterpret the right ones or add unsupported claims.
We therefore design the experience around visible sources, clear uncertainty, and a fallback when evidence is insufficient. For sensitive workflows, a search interface that shows passages directly may be more appropriate than a conversational answer.
What technology options are available?
As of March 2023, we can choose between dedicated vector-search systems, vector capabilities added to existing databases, and managed cloud services.
Examples worth evaluating include Pinecone, Weaviate, Milvus, Qdrant, and PostgreSQL with pgvector. These are not interchangeable. Their deployment models, indexing options, filtering behavior, operational requirements, and pricing differ.
On Google Cloud, our preferred cloud platform, Vertex AI Matching Engine is an option for managed vector similarity search. We would evaluate it alongside the wider ingestion, storage, networking, and application architecture rather than treating it as a standalone answer.
AWS or Azure may be the better fit when an organization already operates there or has specific procurement and compliance requirements.
We shortlist technologies based on the workload: dataset size, update frequency, latency targets, metadata filtering, tenant isolation, and the team's ability to operate the system. A familiar database extension can be a better starting point than a new distributed service.
What architecture would we start with?
For an initial product, we favor a small, understandable architecture. Source content stays in its authoritative system. A background ingestion process prepares records, generates embeddings, and writes searchable entries to a vector index.
Each entry carries a stable identifier linking it back to its source. We also record enough metadata to support filtering, version tracking, and deletion.
An application service receives queries, checks the caller's identity, searches within the authorized scope, and fetches the relevant content. Where supported and appropriate, we apply authorization filters during retrieval; we also verify access before displaying results or sending content to a model.
Updates and deletions need explicit workflows. A deleted source document should not remain discoverable indefinitely through an old vector entry. We define freshness expectations and monitor the synchronization process.
How do we know whether it works?
We do not judge search quality from a handful of impressive demonstrations. We build an evaluation set from realistic tasks and queries, including awkward phrasing, ambiguous requests, exact identifiers, and cases where no relevant answer exists.
Product owners and subject-matter experts help label which results are useful. We compare vector search with the current experience and, where appropriate, a hybrid alternative.
Useful measures include whether a relevant result appears near the top, how long users take to complete a task, and how often the system returns misleading material. Latency matters too, but a fast irrelevant answer is not a success.
We also separate retrieval quality from answer quality. If a generated answer is wrong, we need to know whether the failure came from missing content, poor retrieval, or generation.
This evaluation becomes a regression suite for future changes.
What drives cost and maintenance?
The database bill is only one part of the total. We budget for initial embedding generation, embeddings for new or changed content, query processing, index capacity, application hosting, monitoring, and engineering maintenance.
Breaking documents into smaller passages can improve retrieval precision, but it increases the number of searchable records. More retrieved passages can give a language model additional context, but also increase prompt size and potentially introduce distractions.
Changing embedding models is another important cost. Vectors from different models generally cannot be mixed meaningfully in the same search space. A migration may require re-embedding the corpus, rebuilding indexes, testing quality, and switching traffic carefully.
We therefore record the model and preprocessing version used for each indexed dataset and plan for reprocessing from the start.
What about privacy and security?
Embeddings are derived data, not an automatic anonymization technique. We treat them according to the sensitivity of the information they represent and consider what could be exposed through retrieval.
Before choosing a service, we review where source content and embeddings are processed, who can access them, retention policies, encryption, and relevant contractual requirements.
For multi-tenant products, authorization must be enforced by the system, not by asking a language model to ignore another customer's documents.
If retrieved content is passed to a model, we also treat that content as untrusted input. A document containing instructions should not acquire authority over the application or permission to trigger actions.
A short checklist before we commit
Before approving a vector-search implementation, we confirm that:
- [ ] We have a specific user problem and a baseline to compare against.
- [ ] We have representative queries and agreed relevance criteria.
- [ ] Our source content has clear ownership and usable quality.
- [ ] We have tested exact-match needs and metadata filtering.
- [ ] We have defined access controls, deletion, and freshness requirements.
- [ ] We have estimated ongoing costs, not just prototype costs.
- [ ] We can rebuild the index and change embedding models safely.
- [ ] We have a fallback when the system cannot find useful evidence.
Start with the product outcome
Vector databases are valuable when similarity helps people find or use information more effectively. We recommend beginning with one bounded workflow, proving that retrieval improves the experience, and expanding only when the evidence supports it.
At Kordspace, we bring product design, software engineering, and AI implementation together to make that evaluation practical. To explore a vector-search feature or a broader AI product, start a project with us, or read our related services pages to see how we can collaborate.
Conversation (0)
No comments yet. Start the conversation.
Join the conversation
Create a free member account to comment.