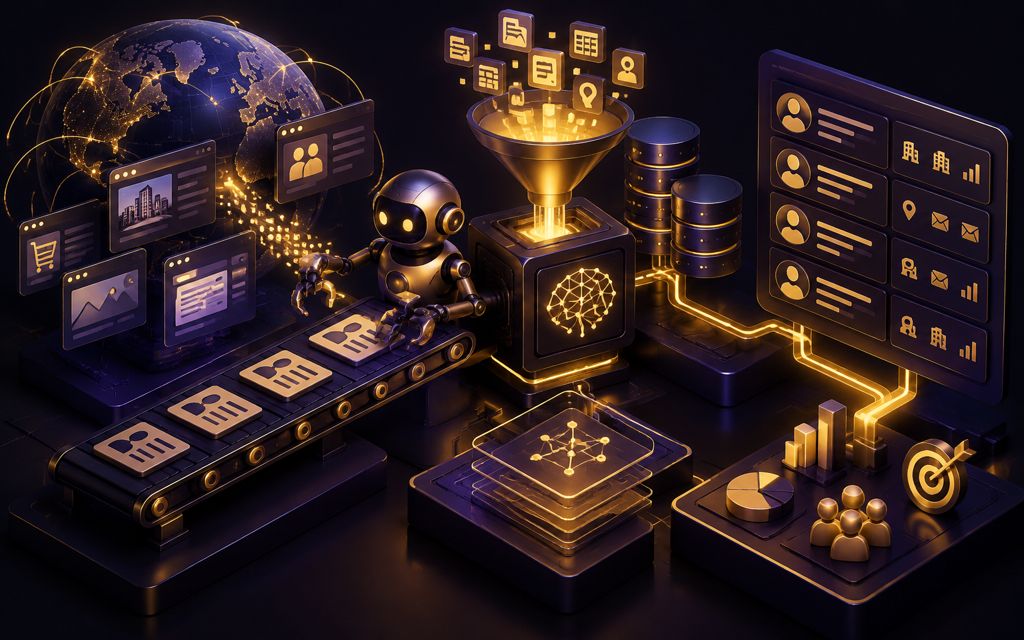
Data Scraper was a Kordspace internal concept focused on lead discovery and business intelligence. Its premise was to turn scattered business information into structured records that could support prospect research and market analysis. Python provided the technical foundation for exploring data collection, extraction, and preparation. The project is best understood as a data-processing prototype rather than a client deployment or a finished commercial product.
The challenge
Business information gathered from different sources can vary in structure, completeness, and usefulness for lead research. A useful scraper needs to distinguish relevant company details from surrounding content while retaining enough context for review. The central design challenge was to make collected information easier to evaluate without treating every extracted field as accurate, current, or appropriate for outreach.
Our approach
The prototype scope centered on a Python workflow for collecting permitted source content and extracting relevant business fields. A practical pipeline separated collection from parsing and normalization so that changes in source structure could be handled independently. Record preparation emphasized consistent field formats, duplicate identification, and source references for manual verification. Structured output formed the handoff between extraction and downstream research, keeping the concept focused on usable data rather than automated sales activity. Responsible collection boundaries included respecting access restrictions and avoiding unnecessary personal information.
The outcome
Data Scraper represented an internal exploration of how data engineering could support lead research and business intelligence. Its value lay in framing extraction as one part of a broader workflow that also required organization, provenance, and human review. The concept provided a foundation for thinking about more advanced data-assisted research tools without implying production readiness or validated commercial results.
Technical highlights
- Python-centered extraction and data-preparation approach
- Separation of source collection from parsing logic
- Normalization and duplicate handling for research-ready records
- Source provenance and human verification as workflow requirements
Place in the journey
2017–2019 Software + CloudData Scraper fits Kordspace's expansion into data-centric software and AI-adjacent workflows. As an internal concept, it connected foundational extraction work with the information-quality requirements of more advanced research systems.